2023
Beyond Pixels: Exploring Human-Readable SVG Generation for Simple Images with Vision Language Models
SVG represents images using explicit shapes, colors, and paths. Beyond Pixels studies how vision-language models can generate vector graphics that retain the meaning of simple images while staying readable to people.
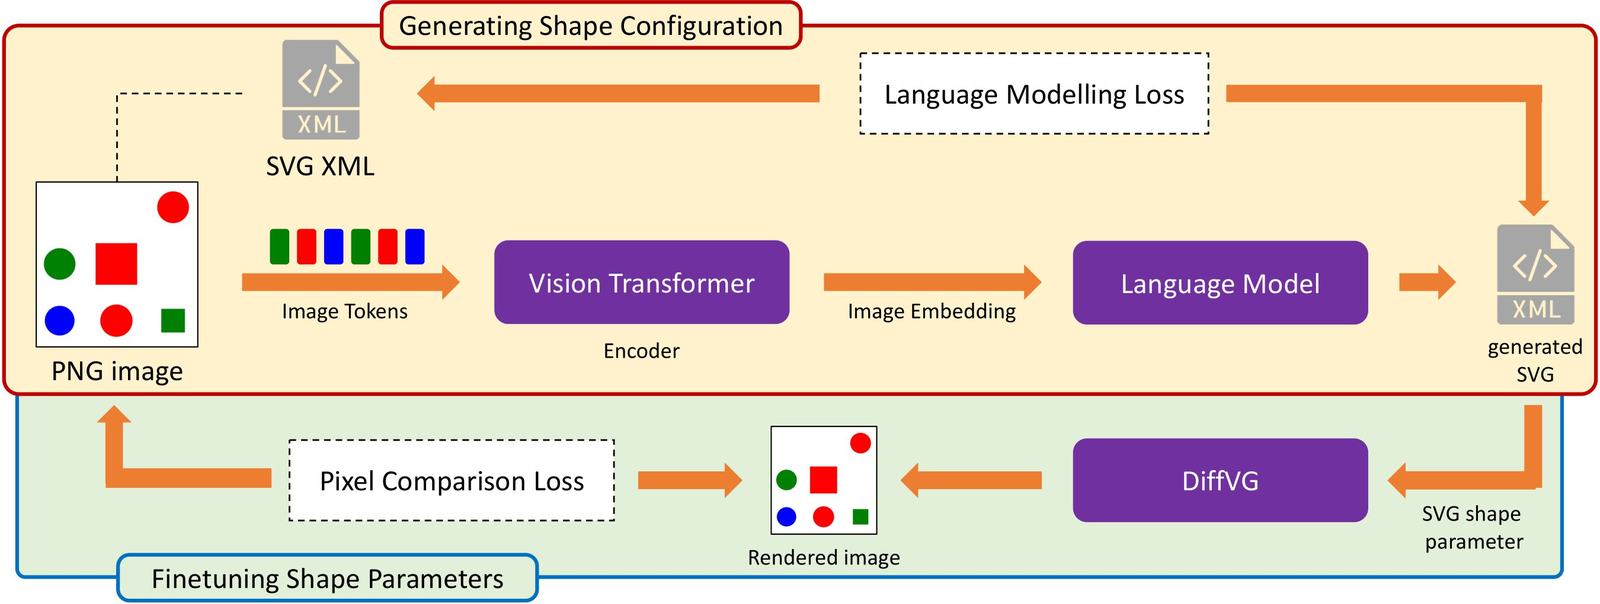
Simple, readable vector graphics
The Simple-SVG-Generation method (S²VG²) targets SVG descriptions that are both visually faithful and understandable. The paper evaluates generated graphics through reasoning tasks and human judgments of readability.
Reasoning from semantic SVG
The latest manuscript includes CLEVR-SVG experiments that evaluate text-only reasoning over generated semantic SVG representations. The linked repository provides the CLEVR-SVG data and evaluation code.
BibTeX
@misc{zhang2023beyondpixels,
  title = {Beyond Pixels: Exploring Human-Readable SVG Generation for Simple Images with Vision Language Models},
  author = {Zhang, Tong and Liu, Haoyang and Zhang, Peiyan and Cheng, Yuxuan and Wang, Haohan},
  year = {2023},
  eprint = {2311.15543},
  archivePrefix = {arXiv},
  primaryClass = {cs.CV},
  url = {https://arxiv.org/abs/2311.15543}
}